ChatGPT’s advertising system in the United States can select audiences from the context of a user’s conversation or from customer and prospect lists supplied by an advertiser. Next INpact reports that the latter can contain email addresses, phone numbers, hashed versions of those identifiers or Google advertising identifiers. For an SME, these are distinct targeting mechanisms: one interprets current demand, while the other attempts to reconnect with known contacts.
Chat context acts as a relevance signal
For contextual targeting, advertisers describe the conversations, subjects or keywords in which their offer would be relevant. The instructions shown to advertisers say that these indications guide matching rather than operate as exact-match targeting rules, according to Next INpact’s account of a test conducted by 404 Media.
That distinction matters operationally. A conventional keyword campaign can be organised around explicit search terms. ChatGPT’s mechanism instead receives a description of situations in which an offer belongs. The system then determines whether the conversation provides a relevant context for the advertisement.
The source does not establish how broadly ChatGPT interprets those descriptions, which conversational signals carry the most weight or how often a relevant discussion results in an impression. Advertisers therefore have a mechanism for expressing intent, but not a published rulebook for predicting every match.
A hypothetical example illustrates the difference. An accounting software provider could describe conversations about preparing invoices separately from conversations about monitoring cash flow. The descriptions would represent different customer needs even though both campaigns promote the same product. They would not guarantee that a specific phrase triggers either advertisement.
Conceptual illustration of contextual ad matching rather than exact keyword selection.
Customer lists provide a separate matching route
Custom audiences do not begin with the subject of the current chat. They begin with identifiers already held by the advertiser. The reported OpenAI documentation accepts customer or prospect lists containing email addresses, phone numbers, hashed email addresses, hashed phone numbers or Google advertising identifiers.
This route serves a different commercial task. Contextual targeting seeks people discussing a relevant need, including people unknown to the advertiser. A custom audience starts from an existing contact record and uses an identifier to support matching. A sales or marketing team should not treat the routes as interchangeable merely because both can lead to an advertisement inside ChatGPT.
The report also says OpenAI tells advertisers that it does not disclose user information to them. That claim describes the direction of data sharing: OpenAI performs the targeting rather than handing the underlying conversation to the advertiser. It does not mean that advertisers supply no personal data, because custom-audience campaigns require them to submit their own contact identifiers.
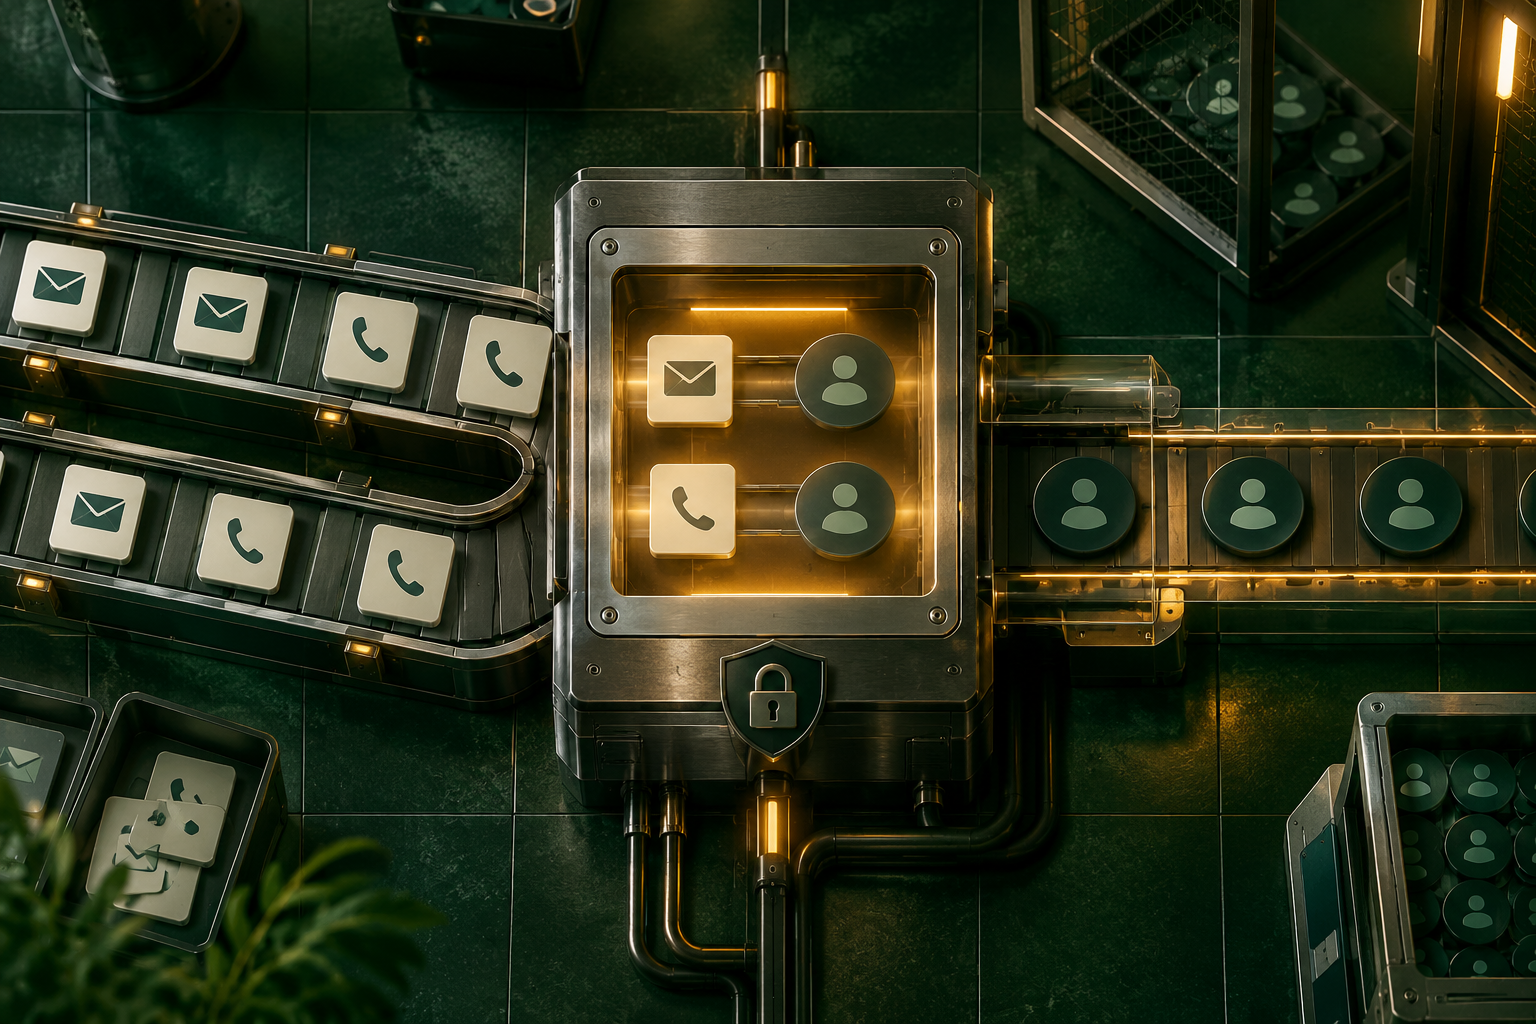
Conceptual illustration of custom-audience matching with contact identifiers.
Campaign structure follows the customer’s situation
OpenAI encourages advertisers to separate campaigns according to the context in which customers need a service. The example reported by Next INpact distinguishes urgent plumbing repairs from preventive maintenance. The business is unchanged, but the customer’s situation and the relevant message differ.
For commercial operations teams, the practical work is therefore not simply exporting a broad contact database or adapting an existing display advertisement. Contextual campaigns require a clear description of the problem being discussed, the circumstances in which the offer is relevant and the boundary between neighbouring needs.
This also limits what the announcement proves. The available report explains the campaign inputs and matching concept, but provides no campaign results, conversion evidence or independent comparison with search and social advertising. The mechanism is concrete; its commercial performance remains undocumented in the supplied evidence.
Unhashed uploads leave a processing question open
The custom-audience form reportedly permits email addresses and phone numbers to be uploaded without prior hashing. When 404 Media asked whether OpenAI hashes identifiers submitted in that form, the company did not answer that question. It said uploaded list files are deleted after processing, normally within 24 hours, as reported by Next INpact.
File deletion and identifier transformation are separate operations. Deleting an uploaded file addresses how long that file remains, while hashing concerns the form in which an identifier enters the matching process. The reported response clarifies the intended deletion window but leaves the second point unresolved for raw uploads.
The immediate choice is specific. An SME can assess contextual targeting against a clearly defined customer situation without uploading its contact list. Using a custom audience requires an additional decision about whether the documented treatment of email addresses and phone numbers is sufficient. The next material evidence to watch is a direct explanation of how unprocessed identifiers are transformed and matched.